Support & sales
How to Triage Support Tickets
Backlogs are a queue design problem, not an effort problem. See how ticket triage, priority rules and SLA discipline keep customer support predictable.
Monday’s tickets wait longer than Wednesday’s. A case is transferred twice because each team assumes somebody else owns it. Agents work continuously while the oldest ticket becomes older. The support manager can report average response time but cannot predict whether a customer writing today will hear back today or three days from now.
This is not proof that the team needs more agents. It is proof that the queue lacks entry discipline, explicit priority and durable ownership. Learning how to triage support tickets means deciding in advance what enters, what order it leaves in, who owns every item and what evidence shows that it was actually resolved.
The backlog is a symptom, not the problem
A backlog is the visible accumulation of earlier operating decisions. It grows when work arrives through channels that are not counted, everything is marked urgent, easy cases are selected ahead of important ones, transfers release ownership, recurring defects generate fresh contact and resolution is confused with closure.
Capacity can be a real constraint. But adding agents before fixing those rules gives more people different ways to interpret the same queue. The business pays for activity while response becomes less consistent and quality harder to compare.
The customer experiences uncertainty: no acknowledgement, repeated explanations, contradictory answers or a ticket closed without the issue being solved. The manager experiences the same system as firefighting: unpredictable ageing, frequent manual reassignment, urgent escalations and no credible staffing forecast.
Diagnose the system before hiring. Measure arrivals, completions and open work by hour, day, channel, category, severity and age. Separate new tickets from reopened and repeat contacts. Look for queues, shifts or issue types where work accumulates. The aggregate backlog number alone cannot reveal the cause.
What ticket management actually covers
Ticket management is an operating discipline, not a helpdesk subscription. It includes:
- intake: bringing supported contact channels into a countable system and preserving their source;
- triage: categorising intent, severity, impact and required skill from observable evidence;
- priority: deciding which work is served first and what target applies;
- ownership and routing: giving one person responsibility while using specialist queues and explicit transfers;
- service levels: measuring first response, meaningful progress and resolution against stated hours;
- escalation: moving exceptions to someone with the authority or expertise to act;
- resolution quality: confirming the answer was accurate, complete, safe and recorded; and
- feedback: using ticket evidence to correct products, policies, content and upstream processes.
A tool can automate assignments and timers only after these rules exist. Otherwise, automation applies ambiguous logic quickly and hides it behind a workflow builder.
Intake: consolidate before you optimise
Email, web forms, chat, phone, social messages and shared inboxes can form one support operation only when every supported interaction creates or updates a case in the system of record. Consolidation does not mean pretending channels behave alike. It means one customer history, one ownership field, one status model and one reporting source.
Start with a channel inventory. For each address, number, form, messaging account and in-product route, record the owner, hours, expected response, volume, data captured, integrations and failure route. Remove obsolete public routes or redirect them clearly. Connect active routes to the helpdesk and test the full path, including attachments, replies, delivery failures and out-of-hours messages.
Phone work needs a case note or linked call record. Social comments that become account-specific need a controlled move to private support, with the public acknowledgement and private case connected. A customer who changes channel should not become a new person merely because the software did not match the record.
Teams often resist because a personal or departmental inbox feels faster. It is faster for the individual who sees it and invisible to everybody else. Use views and notifications to preserve convenient work while keeping the ticket, owner, age and decision record central. A broader multichannel customer support strategy should define which channels exist; queue management begins once they enter the system.
Triage rules a new starter can apply
A triage decision should use four separate fields: category, severity, customer impact and expected effort. Combining them into one vague priority label produces inconsistency.
- Category describes the work: account access, payment, delivery, product defect, setup, cancellation, privacy request or another maintained taxonomy. It routes skills and reveals recurring demand.
- Severity describes operational consequence using observable criteria: safety or security risk, complete service loss, material data exposure, transaction failure or a routine question.
- Customer impact records breadth and importance: one user or many; workaround available or absent; time-critical business process blocked or merely inconvenient.
- Effort estimates the handling path: immediate known answer, standard investigation, specialist diagnosis or coordinated incident. Effort informs staffing but should not overrule severity.
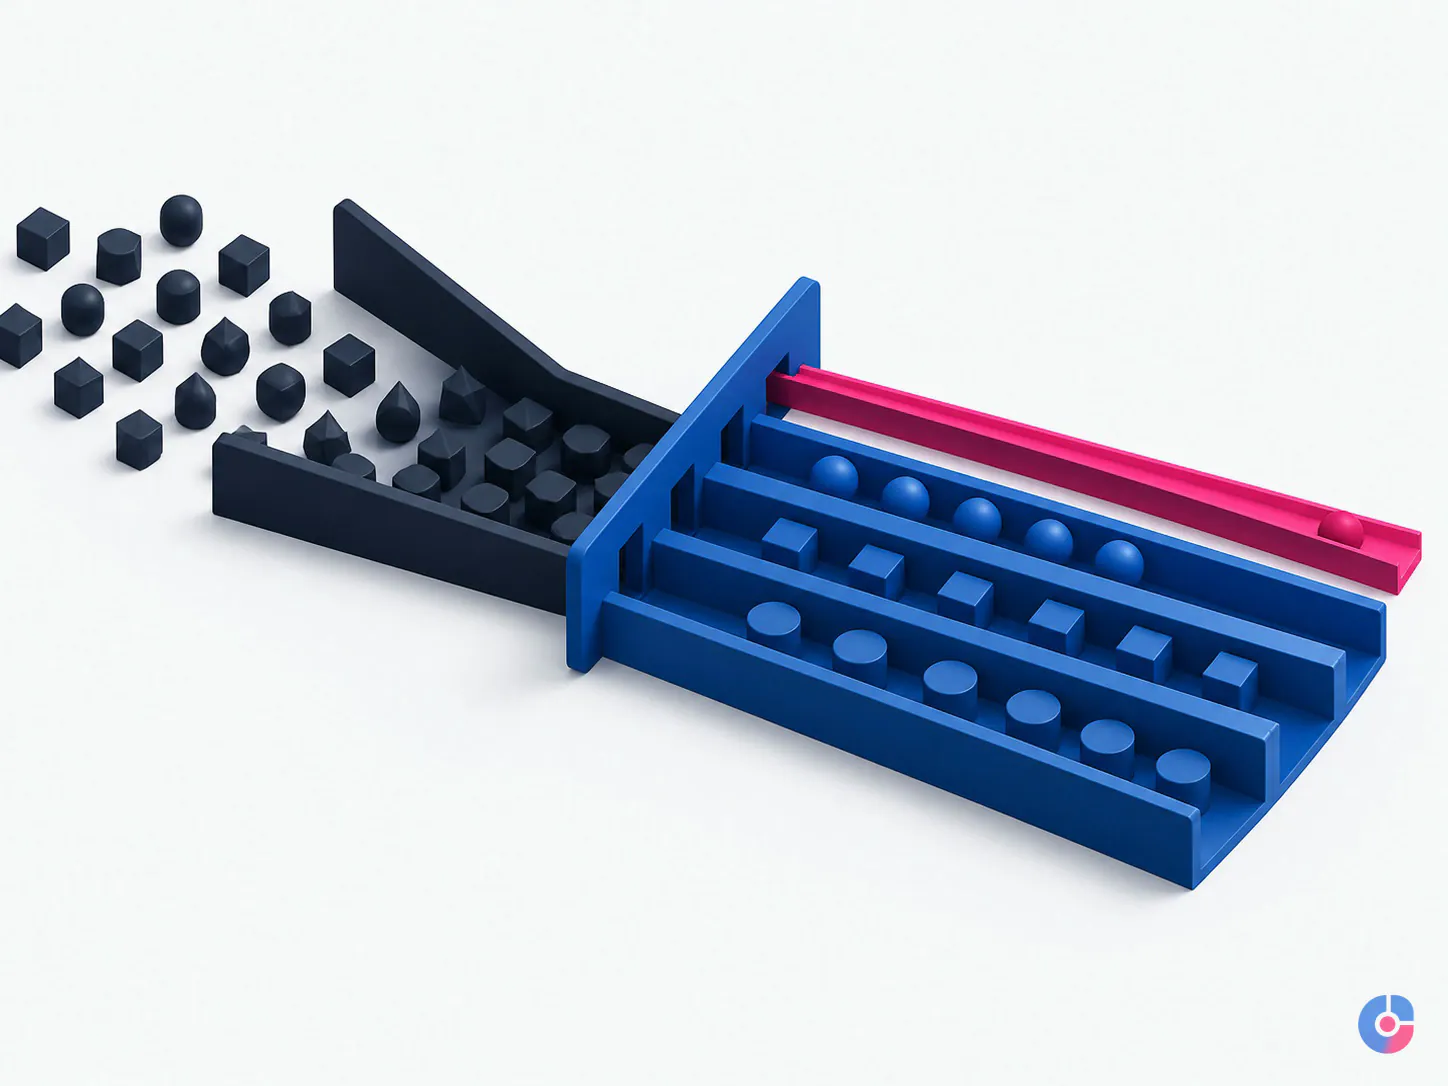
Define severity with testable statements. A starting model might be:
| Level | Observable entry criteria | Routing response |
|---|---|---|
| S1 critical | Credible immediate safety or security risk; confirmed material data exposure; or widespread complete failure of a critical service with no workaround | Incident route now; notify named authority; assign an incident owner; keep the customer case linked |
| S2 high | Critical function unavailable for one or more customers, material transaction or deadline blocked, and no reasonable workaround | Senior support or specialist queue; rapid first acknowledgement; timed internal escalation |
| S3 normal | Function degraded, standard error or service request with a workaround or limited impact | Appropriate functional queue in normal priority order |
| S4 low | Information request, cosmetic issue, suggestion or non-urgent administration with no current service impact | Standard queue, self-service answer where useful, or planned product feedback route |
Adapt the criteria to the business and validate them with real examples. Do not allow revenue, seniority or the word “urgent” alone to define technical severity. Commercial priority can be a separate, visible factor. This prevents an executive’s minor request from silently displacing a service failure.
The triager confirms required identity and information, removes obvious duplicates, links known incidents, applies fields, assigns the right queue and records the reason for elevated severity. Missing information should trigger a standard request, not indefinite limbo.
The two-minute rule, and why it is not always right
Resolving a trivial case during triage can keep the queue clean and spare a second person from rereading it. Use that rule only when the answer is genuinely known, permissions allow it and no higher-severity or near-breach case is being displaced.
“Quick wins first” becomes queue avoidance when agents repeatedly select easy password or status questions while complex older cases age. Time-box the immediate-resolution lane, monitor cherry-picking and keep service-level risk visible in the same view.
Priority is a promise, so write it down
A service-level target means nothing unless its timer, hours, stop conditions and owner are defined. Set separate targets for first response and resolution by severity or supported request class. First response should be a meaningful acknowledgement that confirms ownership or the next step, not an automated receipt presented as agent work.
Define whether targets run in staffed business hours or continuously. Publish the business calendar, time zone, holidays and out-of-hours incident route. Do not compare a queue measured in business hours with one measured by elapsed clock time.
Resolution targets need exceptions because some cases wait legitimately for customer evidence, a vendor or an engineering change. Use controlled statuses with reason codes and ageing rules. Pausing a timer must not make a case disappear; report customer-waiting and third-party-waiting age separately.
Make approaching breaches visible during the shift. Review actual breaches weekly, not only in a monthly dashboard. For each one, record whether the cause was arrival spike, routing error, missing ownership, staffing gap, unavailable expertise, approval delay, system failure or incorrect target. A target without a corrective loop is merely a retrospective colour.

Ownership is the most common failure
Every ticket needs one named owner at all times. A queue can identify the responsible team, but a queue is not a person. The owner is accountable for the next customer update, internal follow-up, accurate status and closure evidence even when a specialist performs part of the work.
Reassignment is an explicit act. The receiving person or controlled routing rule accepts it, the reason is recorded and the previous owner does not disappear until the handoff is complete. “I added engineering” is not a transfer unless somebody owns the customer communication.
Build three views: unassigned tickets, tickets without a future action or update time, and owned tickets where the owner is absent. Review them at shift start and handover. For time zones or follow-the-sun coverage, transfer ownership in a structured handoff with summary, actions taken, evidence, risks and next promised update.
OVELITHUB’s ticket management services can be scoped around triage, queue ownership, SOPs, multichannel intake and weekly quality review. The client retains policy, exception authority and specialist escalation. Book a support operations review with an export of the current backlog and status definitions.
Reduce what enters the queue
The lowest-cost valid contact is the one prevented by a clearer product, process or timely message. That does not mean hiding the support route or forcing a customer through irrelevant articles. It means learning from repeated demand.
Each week, rank contact reasons by new volume, repeat contact and handling effort. Sample the top reasons and ask:
- Is the underlying product, delivery, billing or policy defect removable?
- Can the interface explain status or required action at the point of confusion?
- Would a confirmation or proactive delay message prevent the question?
- Can a help-centre article answer the exact question using current screenshots and a clear escalation route?
- Does the support form collect the diagnostic information the agent asks for every time?
Write articles from actual questions and vocabulary. Include scope, prerequisites, steps, expected result, common failure and a route to a person. Give each article an owner and review trigger. Search terms with no result and articles followed immediately by contact are useful signals that content is missing or not solving the problem.
Measure prevention carefully. A fall in tickets is not automatically success: the form may be broken, the contact link hidden or customers may have abandoned the attempt. Pair contact rate with task completion, unresolved feedback, repeat behaviour and business outcomes. Make assisted support easy to reach when self-service fails.
For a known incident, publish an accurate status message and link related tickets. This reduces duplicate investigation while preserving affected-customer records. When resolved, explain the next action rather than closing every case with the same generic sentence.
Quality, not just speed
Use measures that prevent speed from becoming premature closure:
- Reopen rate: tickets reopened after closure, segmented by category and agent, with reasons sampled.
- Repeat contact: a second interaction about the same issue within a defined window, including contacts that create a new ticket.
- Escalation rate and reason: correct escalation can be good judgment; avoidable escalation reveals a knowledge, access or authority gap.
- Resolved-ticket satisfaction: feedback attached to the specific interaction and interpreted alongside response rate and issue type.
- Quality review: sampled cases scored for diagnosis, accuracy, ownership, tone, documentation, data handling and complete resolution.
- Service-level performance: first response and resolution compliance by severity, channel and operating hours, including breach cause.
Average handling time is a capacity input, not a standalone quality measure. Optimising it in isolation rewards fast transfers, thin notes and closure before confirmation. Examine its distribution by contact type. A change may reflect a new product fault, tool friction, learning need or rushing; the number cannot explain itself.
Staff the queue from arrival patterns
Forecast arrivals by interval, day, channel, category and season. Add reopening and follow-up work, meetings, training, quality review, absence and non-ticket tasks. Use your own median and percentile handling distributions by issue type rather than a universal “tickets per agent” assumption.
Coverage should follow customer demand and service promises. A short peak may need staggered shifts or a flexible triage role; it does not automatically justify constant staffing. Out-of-hours coverage may focus on critical incidents while routine tickets wait under a published business-hours target.
An outsourced or offshore team can extend coverage and create dedicated queue capacity, but it increases the need for current documentation, secure access, product training, calibration and responsive escalation. The client should retain the severity policy, exception authority, knowledge owners and quality rubric. Tier-two work can move only when diagnosis, tools and engineering handoffs are mature. General commercial considerations belong in the separate helpdesk support outsourcing guide.
Access, data protection and audit
Give agents named accounts and the minimum helpdesk role required. Separate content administration, workflow administration, user management and export permission from routine ticket handling. Require multi-factor authentication where supported, review role changes and revoke access promptly at offboarding.
Tickets can contain addresses, identifiers, account history, health details, payment references and attachments the organisation did not ask the customer to send. Define what may be collected, which fields hold it, who can view or export it, when redaction is required and how long records are kept. Do not copy sensitive data into internal chat merely to speed an escalation. Use the approved case or protected escalation route.
Where an external provider processes UK-regulated personal data for the business, current ICO controller–processor contract guidance requires a written contract or other legal act and lists minimum terms covering documented instructions, confidentiality, security, subprocessors, individual-rights assistance, incident and assessment support, audits, and end-of-contract return or deletion. Other countries and regulated sectors impose additional requirements. Map the applicable jurisdictions, transfer mechanism, retention, monitoring and incident responsibilities with qualified advisers before access begins.
Keep an audit trail for assignment, status, priority changes, merges, redaction, views or exports where the platform supports them, customer updates and closure. Limit bulk export. Test restored access and case continuity during planned absence and provider offboarding.
Clear an existing backlog in parallel
Do not stop new work and ask the whole team to “clear the backlog.” New tickets then become the next backlog. Create two controlled tracks.
- Protect a current-work team or time block that triages new arrivals and maintains the new service rule.
- Run a backlog sweep to remove spam and exact duplicates, link known incidents, identify already resolved contacts and apply current severity and ownership.
- Contact old-ticket customers with a truthful status check where needed; do not assume silence means resolution.
- Assign a backlog cell by category so people build context instead of sampling random old cases.
- Set an age-based review for cases waiting on customers, vendors or internal specialists.
- Track arrivals, valid closures, reopens and oldest age daily until normal work absorbs the remaining queue.
Analyse why old cases survived. If most were unowned, fix assignment. If they waited for engineering, define escalation capacity and customer updates. If they were low-value duplicates, correct the product or communication. A one-time clearance without structural change merely resets the date of the next crisis.
Fix the queue before adding people
Consolidate intake, classify observable impact, write the priority promise, assign one owner, expose approaching breaches and feed recurring demand back into the business. Then capacity planning has stable work to measure. More agents can help a disciplined queue; they cannot substitute for one.
Keep reading
Related insights
Sales Admin Tasks to Hand Off First
Reps lose selling hours to quotes, CRM updates and scheduling. See which sales admin tasks to hand off, in what order, and…
Outsourced SDR vs In-House Hiring
Outbound stalls when nobody owns it full time. Compare outsourced sales development with hiring an SDR, and see what each option really…
Running Handovers Across Time Zones
Adding a second time zone does not create coverage on its own. Build the handover, the shared record and the escalation path…